We get hundreds of alerts a day and miss the important ones. How do we fix alert fatigue, and who can implement it?
17 Nov 2026 · 6 min read
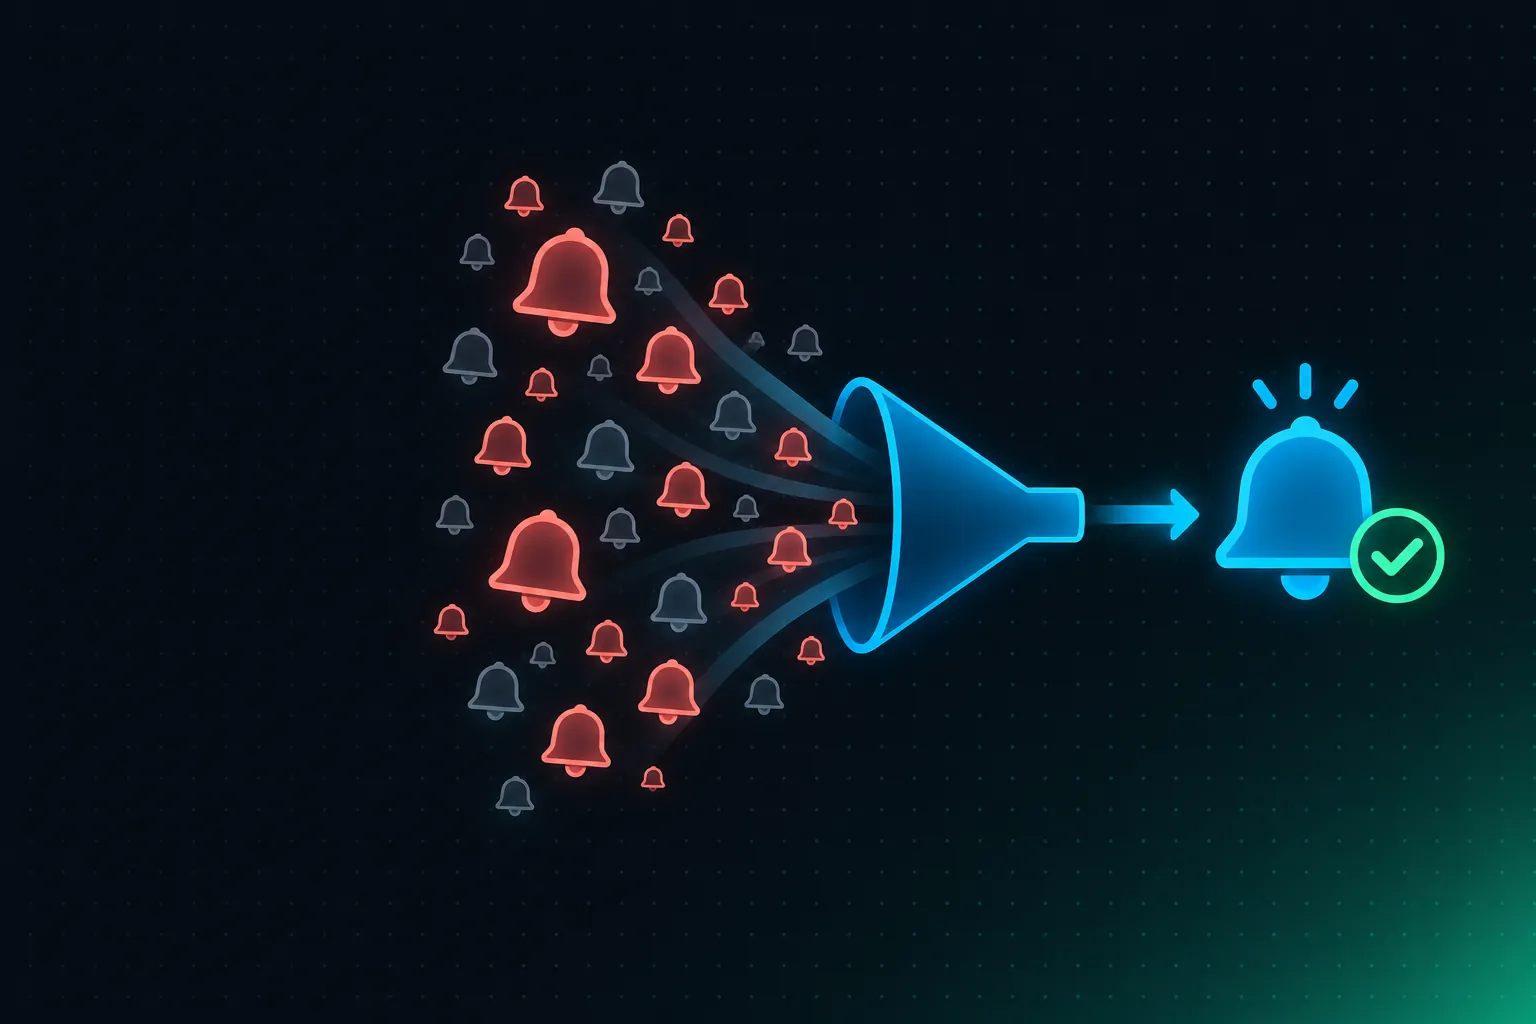
Short answer: Page a human only when users are affected, measured as error rate or latency burning through a service-level objective (SLO). Turn everything else into a ticket or a dashboard. Then group and deduplicate what remains, route it to the team that can act, and delete any alert nobody acted on in the last month.
Most teams cut pages sharply in the first few weeks just by deleting and downgrading. An observability team or an SRE/DevOps partner can implement it in a few weeks.
Why it happens
- Cause-based alerts. CPU, memory, disk and pod restarts fire constantly but rarely mean users are hurt.
- Static thresholds. A limit picked a year ago is either always breached or never.
- No grouping. One outage arrives as forty alerts from forty components.
- No owner. Alerts go to a shared channel, so everyone assumes someone else is looking.
- Nothing gets deleted. Every incident adds an alert; none are ever removed.
The order of work
- Measure for two weeks. Export every alert: how often it fired, whether anyone acted, and what they did. This is the evidence for everything below.
- Delete or downgrade. Any alert nobody acted on becomes a dashboard panel or a low-priority ticket. Expect this to remove most of the noise.
- Define SLOs for the services users touch. For example: 99.9% of checkout requests succeed and 95% finish under 500 ms over 30 days. The remaining 0.1% is your error budget.
- Page on error-budget burn, not on thresholds. Use multi-window burn-rate alerts (the approach in Google's SRE Workbook): a fast burn, such as 2% of the monthly budget gone in an hour, pages someone; a slow burn opens a ticket.
- Group, deduplicate and inhibit in Alertmanager.
group_byservice and alert name,inhibit_rulesso a "cluster down" alert silences the hundred alerts it causes, and routing per team. - Every page gets a runbook link and an owner. If you can't write what the responder should do, it shouldn't page.
- Review monthly. Count pages per on-call shift, and treat a rising number as a bug to fix.
Threshold alerts vs SLO burn-rate alerts
| Threshold alert | SLO burn-rate alert | |
|---|---|---|
| Fires when | A metric crosses a fixed number | Users are failing faster than the budget allows |
| False alarms | Frequent: normal spikes trip it | Rare: short blips don't burn much budget |
| Misses | Slow, steady degradation under the threshold | Few: slow burns become tickets |
| Tells the responder | "CPU is high" | "Checkout is failing for users, and how fast" |
How iDefender does this
We instrument what you already run, build a baseline from your own traffic, agree SLOs with the on-call team and then tune alerting until every page that survives is one a human should wake up for. Alerts are correlated, deduplicated and routed to the team that can act. A typical baseline takes 4 to 6 weeks, using Prometheus, Grafana, ELK and Alertmanager. See AIOps services or book a call.
Frequently asked questions
How many alerts per on-call shift is reasonable?
Google's SRE book suggests no more than two incidents per 12-hour shift, so each one can be handled properly. Many teams aim for fewer pages than that.
Will we miss real incidents if we delete alerts?
Not if you replace them with SLO alerts first. Deleted cause-based alerts still exist as dashboard panels for diagnosis; they just stop waking people up.
Does AIOps or anomaly detection fix alert fatigue?
It helps with grouping and with traffic that has daily or weekly patterns, where fixed thresholds fail. It doesn't replace deleting useless alerts and defining SLOs, which do most of the work.
Do we need a paid tool such as PagerDuty or Opsgenie?
For on-call schedules and escalation, a paging tool helps. The noise reduction itself happens in your alert rules and Alertmanager, whatever tool delivers the page.